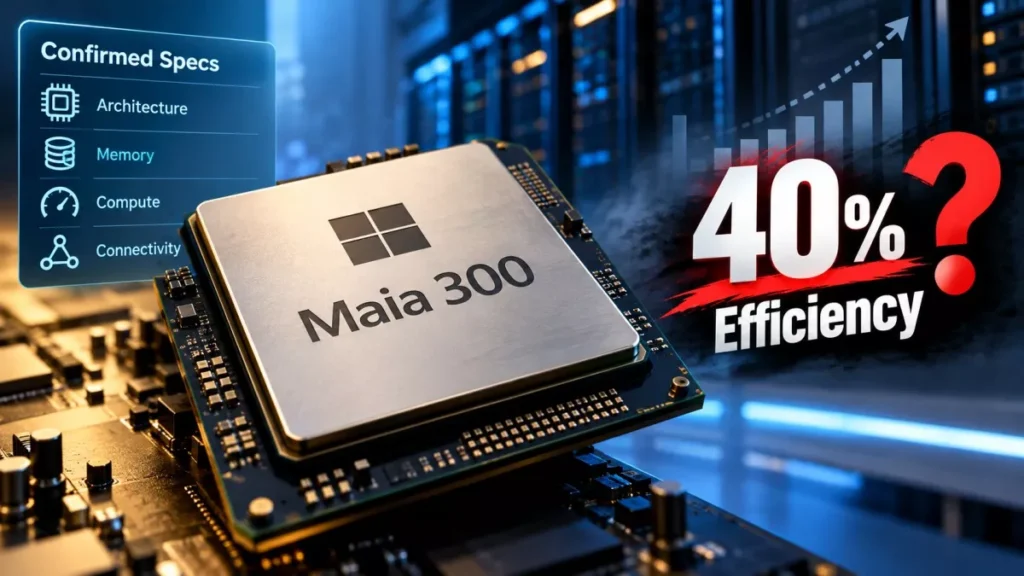
Microsoft announced Maia 300, the third generation of its custom AI accelerator, on 12 October 2026. Each chip carries eight HBM4 stacks totalling 288GB at 18TB/s within a 950-watt power envelope, and 96 of them fill a 167-kilowatt rack. Production deployments do not begin until 2027.
What Microsoft Announced
Maia 300 is an inference accelerator, meaning it is built to generate answers from trained models rather than to train them. Scott Guthrie, Microsoft’s executive vice president for Cloud and AI, set out the plan in a company blog post.
Guthrie wrote that Microsoft “will scale our Azure Maia family to multi-gigawatt deployments starting in 2027, making Maia the primary inference system for Microsoft products and services”. That is the substance of the announcement: not a product anyone can buy, but a declaration that Microsoft intends to run most of its own inference on its own silicon.
The chip Microsoft already uses, Maia 200, went into production earlier in 2026 and is deploying across the United States, Europe and Australia. Microsoft says it serves workloads including Copilot, and that GitHub Copilot and Microsoft Foundry will run on it by the end of 2026.
The Confirmed Maia 300 Specifications
These figures come from Microsoft’s own announcement and its architecture deep dive, so they are the company’s stated design specifications rather than measured results.
| Specification | Maia 300 |
|---|---|
| Memory | Eight HBM4 stacks, 288GB per accelerator |
| Memory bandwidth | 18TB/s peak |
| Power envelope | 950-watt TDP |
| Compute process | TSMC N2P for the compute chiplets |
| Packaging | Multi-chiplet, with memory-controller and I/O on separate dies |
| Accelerators per rack | 96, in 24 four-accelerator trays |
| Rack power | 167 kilowatts |
| HBM per rack | 27.6TB capacity, 1.7PB/s aggregate bandwidth |
| Largest cluster | Up to 12,288 accelerators across up to 128 racks |
Microsoft’s deep dive states the memory configuration as “eight HBM4 stacks providing 288 GB of capacity and 18 TB/s of bandwidth per accelerator”. Reporting by Notebookcheck puts peak compute at 13.8 PFLOPS at FP4 and 6.9 PFLOPS at FP8, with the HBM4 running at 9 Gb/s per pin; Microsoft has not published compute throughput figures itself.
Which Performance Claims Name a Baseline
This is where the announcement needs reading carefully. Microsoft’s generation-on-generation claims specify what they are measured against; its headline efficiency claim does not.
| Claim | Baseline named |
|---|---|
| Up to 7x rack-scale token throughput | Yes — Maia 200, in the 96-accelerator configuration |
| More than 2.5x performance per watt | Yes — Maia 200 |
| 2.5x memory bandwidth | Yes — Maia 200 |
| 33% more memory capacity | Yes — Maia 200 |
| About 2x HBM bandwidth per watt | Yes — Maia 200 |
| Doubled accelerator density per rack | Yes — Maia 200 |
| 40% more tokens per megawatt | No — “leading GPU-based systems”, not identified |
| 36% more system compute FLOPs | No — baseline not named |
| 14% more scale-up bandwidth | No — baseline not named |
Microsoft’s exact wording on the efficiency figure is that “we expect Maia 300 to deliver 40% more tokens per megawatt compared to leading GPU-based systems”. Three things follow from that phrasing. It is an expectation, not a measurement. The comparison system is unnamed, so no one outside Microsoft can reproduce it. And because it is stated per megawatt rather than per chip, it is a claim about whole-rack efficiency, which depends on the cooling and power design as much as on the silicon.
The generation-on-generation numbers are more useful precisely because the baseline is a known product. A site cannot check them either, but it can at least see what is being compared. This is the same reporting problem as the China AI chip cluster plan published without a date, model or benchmark.
How the Rack and the Superpod Are Built
Microsoft’s argument is that Maia 300 is a rack design rather than a chip, and the published detail supports that framing.
- Tray layout: 96 accelerators sit in 24 trays of four, inside a 167-kilowatt rack.
- Switching: Six high-radix switch ASICs occupy three liquid-cooled switch trays.
- Power delivery: A 50-volt busbar architecture with dual power feeds.
- Cooling: Microsoft says liquid cooling removes “more than 80% of the rack’s thermal load” from the accelerators, voltage regulators and switch ASICs.
- Networking: A custom AI transport protocol built on Ethernet. Links inside a rack are electrical; the second tier between racks is optical.
- Superpod: Up to 128 racks combine into a cluster of 12,288 accelerators, with three latency tiers depending on whether traffic stays in a pair, a pod, or crosses pods.
- Peer bandwidth: An accelerator can drive up to 750GB/s to any peer in the superpod when only some accelerators are communicating across racks.
What Changed From Maia 200
Maia 200 launched in January 2026 on TSMC’s 3nm process with 216GB of HBM3E, 7TB/s of bandwidth and a 750-watt rating. Maia 300 raises all three figures and adds 200 watts.
The architectural change is in how memory is addressed. Maia 200 introduced what Microsoft calls its Software Defined Locally Accessed Dataflow Architecture, in which software rather than hardware decides where data sits and how it moves between on-die SRAM, DMA engines, HBM and the network. Maia 300 shifts that memory from a uniform layout to a non-uniform one across chiplets, so software can place data near the compute unit that will use it. Microsoft has not published the SRAM capacity.
The chip also supports what Microsoft describes as enhanced MXFP4 and sub-3-bit storage formats. Compressing values that aggressively shrinks the key-value cache, which is the memory a model uses to remember a conversation, and that in turn allows longer context windows on the same hardware.
Where Maia 300 Stands Against Nvidia
Microsoft does not mention Nvidia anywhere in its announcement; GPUs appear only as an unnamed comparison baseline. The closest direct comparison in launch-day reporting comes from SiliconANGLE, which notes that Maia 300 matches the 288GB HBM4 capacity of Nvidia’s Rubin accelerator but has roughly 20% less memory bandwidth.
That single data point does not settle anything, and no independent benchmark of Maia 300 against any Nvidia product exists. Microsoft also continues to buy Nvidia hardware; nothing in this announcement says otherwise. Reuters reported that Microsoft could deploy more than a million Maia chips next year, a figure Microsoft’s own posts do not state.
When Anyone Can Actually Use It
As of 13 October 2026, Maia 300 is an announcement, not a product in service: Microsoft says production deployments begin in 2027 and has published no availability date, region list or pricing.
Nor has Microsoft said whether Azure customers will be able to rent Maia 300 capacity directly, as they can with Nvidia GPUs. Every named workload so far is a Microsoft product: Copilot, Teams, Cowork, GitHub Copilot and Microsoft Foundry. If Maia 300 does reduce the cost of serving tokens, the first effect reaches users as the economics of those products rather than as a chip anyone else can book, which is the backdrop to moves such as the $10 default usage limit on Microsoft 365 Copilot Business and the wider round of AI API price cuts.
Microsoft says it will give more detail on its AI strategy at Microsoft Ignite 2026 in November.
What Microsoft Did Not Disclose
- Compute throughput: No FP4 or FP8 FLOPs figures in Microsoft’s own posts.
- SRAM capacity: Described only as software-managed on-die SRAM.
- Chiplet count: The deep dive confirms separate compute, memory-controller and I/O dies but gives no number. SiliconANGLE reports four compute chiplets, one device control chiplet and two auxiliary chiplets for data movement.
- Total deployment size: “Multi-gigawatt” is the only figure; no chip count is given.
- The GPU baseline: Which systems the 40% claim was measured against.
- Customer access and price: Neither has been addressed.
Maia 300 FAQ
When Will Maia 300 Be Available?
Microsoft says production deployments start in 2027. It has not given a month, a region or a general availability date.
What Does Maia 300 Do?
It runs inference, the stage where a trained model produces output for a query. Microsoft intends it to become the main hardware serving its own AI products rather than a training chip.
Is Maia 300 Faster Than an Nvidia GPU?
No independent benchmark exists. Microsoft claims 40% more tokens per megawatt than unnamed leading GPU-based systems, and SiliconANGLE reports the chip has about 20% less memory bandwidth than Nvidia’s Rubin despite matching its 288GB of HBM4.
Can Azure Customers Rent Maia 300?
Microsoft has not said. Every workload it has named is one of its own products, and no customer pricing or access terms have been published.
How Much Power Does a Maia 300 Rack Use?
167 kilowatts for 96 accelerators, each rated at a 950-watt TDP. Liquid cooling handles more than 80% of the rack’s heat, according to Microsoft.
What Is the Difference Between Maia 200 and Maia 300?
Maia 300 moves to TSMC’s N2P process from 3nm, raises memory from 216GB of HBM3E to 288GB of HBM4, lifts bandwidth from 7TB/s to 18TB/s, and doubles the accelerators in a rack. Its power rating rises from 750 to 950 watts.