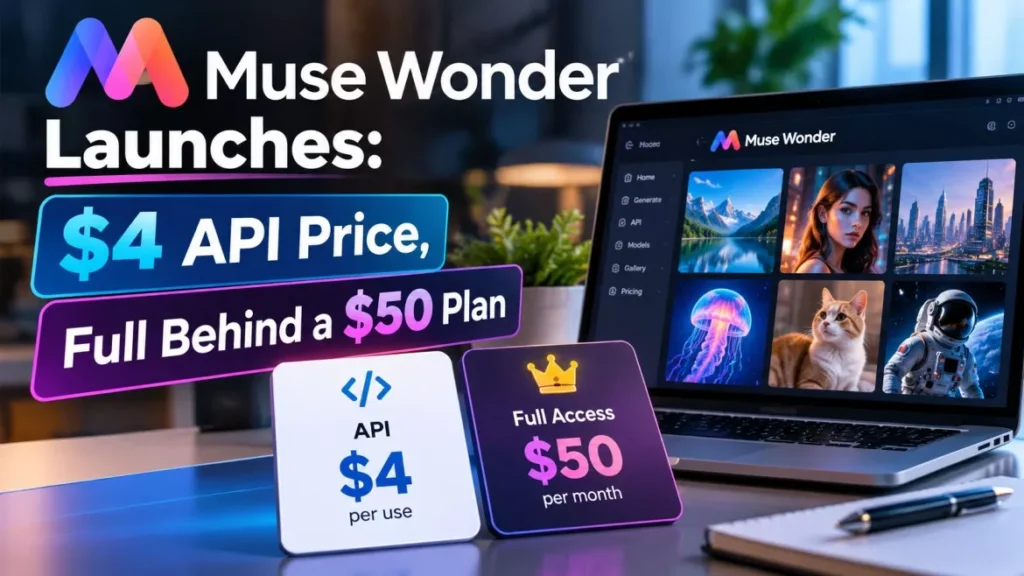
Meta released Muse Wonder and Muse Wonder Full on 12 October 2026, its first frontier-class models. Muse Wonder costs $4 per million input tokens and $20 per million output tokens on Meta’s API. Muse Wonder Full, the stronger of the two, is not sold by the token at all.
What Meta Released
Muse Wonder and Muse Wonder Full are two proprietary models from Meta Superintelligence Labs, the AI division Meta restructured in August 2025 under Alexandr Wang, the former chief executive of Scale AI.
Both accept text, images, audio and video and return text, and both carry a context window of about one million tokens — the amount of material a model can hold in view at once. Meta trained them at its Prometheus data centre, which TechCrunch reports is in central Ohio and came online earlier in 2026. Meta has not disclosed how many parameters either model has, and neither can be downloaded or self-hosted.
They sit above Muse Spark, the faster, cheaper family Meta launched in April 2026, and they are intended to drive Muse, the personal agent Meta launched in September.
Which Model You Get, and What It Costs
The access route decides which model you get: the API gives you only the weaker model, and the stronger one requires a Muse Code subscription.
| Access route | Model you get | Price | Is your input used for training? |
|---|---|---|---|
| Meta Model API (pay as you go) | Muse Wonder only | $4 per million input tokens; $20 per million output; $0.20 cached input | No — Meta says API traffic runs in standard mode |
| Muse Code, Power Usage | Muse Wonder and Muse Wonder Full | $50 a month | Yes by default, under contributor mode |
| Muse Code, Maximum Usage | Muse Wonder and Muse Wonder Full | $200 a month | Yes by default, under contributor mode |
Meta’s announcement puts it plainly: Muse Wonder is “available today for developers and builders through the Meta Model API and Muse Code”, while Muse Wonder Full is available today for Muse Code subscribers. The API model identifier is muse-wonder-1.0, and VentureBeat reports rate ceilings of 3,000 requests and four million tokens a minute.
On a per-token basis the standard model is priced level with Anthropic’s Claude Opus 5.5 at $4 and $20, and well below OpenAI’s GPT-6 Astra at $10 and $50, according to the comparison VentureBeat compiled. Cheaper tokens do not guarantee a cheaper finished job, because a model that takes more steps to reach an answer spends more of them.
This is the second frontier model in two weeks to launch with its best version fenced off, after Google restricted Gemini 4 Argon to 650 partners.
How Muse Wonder Scores Against Opus 5.5 and GPT-6 Astra
On the one scoreboard Meta does not control, Muse Wonder Full comes fourth rather than first. Artificial Analysis, an independent benchmarking firm, scores Muse Wonder Full at 56 on its Intelligence Index, ranking it fourth of 689 models. The standard Muse Wonder scores 52.
- Claude Opus 5.5: 58, the highest of the group.
- Claude Sonnet 5.5: 56, level with Muse Wonder Full on the rounded figure.
- Muse Wonder Full: 56.
- GPT-6 Astra, Gemini 4 Argon and Claude Fable 5.1: 53 each.
- Muse Wonder: 52.
Meta’s own model card tells a more favourable story on specific tasks. It puts Muse Wonder Full at 57.5 on SWE-Marathon, a long-running coding test, against 46.3 for Opus 5.5, and at 13.1 on the Harvey LAB-AA legal benchmark against 4.2. Those are Meta-reported numbers, taken at maximum reasoning effort, and Meta acknowledges the coding comparison was not run under identical conditions because the models used different coding tools.
Opus 5.5 still leads several rows of Meta’s own table, including Terminal-Bench and HealthBench Pro, and Meta has not published how its Personal Superintelligence Index is calculated, so that figure cannot be checked independently.
What Active Memory and Active Focus Do
These are the two features Meta puts at the centre of the release, and both concern long tasks rather than single answers.
Meta describes Active Memory as “the ability to carry what matters to you across conversations”, bringing back details relevant to the task at hand instead of starting cold each session. Active Focus it describes as “the ability to keep working toward your goal when a task gets hard” — trying other approaches, recovering from errors and seeing a job through.
Meta also says the models ask for clarification when they need it and check in before acting on anything important, which is a design choice about agents taking consequential actions rather than a performance claim.
What Meta Trains On by Default
Muse Code subscriptions default to a setting Meta calls contributor mode, under which Meta may use the prompts, code, files and outputs passing through the tool to improve its models.
The default can be changed, but the opt-out applies only to future submissions, not to material already sent. Traffic through the pay-as-you-go API is treated differently: Meta says standard mode content is not used for training. Zero data retention exists as a separate arrangement for approved organisations, and VentureBeat reports it comes with real limits — no server-side conversation state, no background requests, no file uploads and no built-in web search.
There is a genuine conflict in the record here. When Meta launched Muse Code in August 2026, CNBC quoted Alexandr Wang describing the cheapest tier as one where developers “opt-in to help improve the model”, which reads as the opposite of a default. The reports from this week describe what a new subscription actually does rather than what the policy says it does. Anyone paying $50 or $200 a month for client work should check the setting in their own account rather than rely on either account.
What Meta Has Not Disclosed
As of 14 October 2026, Muse Wonder is the only one of the two models available on Meta’s API, Muse Wonder Full is available solely inside Muse Code, and Meta has not said whether that will change. Several other things are missing.
- A price for Muse Wonder Full: There is no published per-token rate, only the subscription tiers that include it.
- Parameter counts: Not disclosed for either model.
- Regional availability: Meta’s announcement contains no country or region detail, and no list of markets where Muse Code is sold.
- The full safety report: Meta says the models carry its strongest safeguards yet against chemical, biological, radiological and nuclear misuse and against cyber misuse, and that “a full report with additional safety evaluations will be available soon”. That report is not out.
- Index methodology: The calculation behind Meta’s own Personal Superintelligence Index is unpublished.
Meta’s commercial plans around these models are also only partly drawn: its enterprise platform launched in September without prices or dates, and the Wonder release does not fill that gap in.
Frequently Asked Questions
How Much Does Muse Wonder Cost?
Muse Wonder costs $4 per million input tokens, $20 per million output tokens and $0.20 per million cached input tokens on Meta’s Model API. Muse Wonder Full has no per-token price and comes with Muse Code plans at $50 or $200 a month.
Can I Use Muse Wonder Full Through the API?
No. Meta does not serve Muse Wonder Full through the Meta Model API, and Artificial Analysis lists it as having no publicly available API. A Muse Code subscription is the only route to it.
Does Meta Train on What I Send to Muse Code?
By default, yes. Muse Code subscriptions start in contributor mode, which permits Meta to use prompts, code, files and outputs to improve its models. The setting can be turned off, but only for material submitted after the change.
How Does Muse Wonder Compare With Claude Opus 5.5?
On Artificial Analysis’s Intelligence Index, Muse Wonder Full scores 56 against 58 for Claude Opus 5.5. On Meta’s own benchmarks, Muse Wonder Full leads Opus 5.5 on long coding and legal tasks while trailing it on Terminal-Bench and HealthBench Pro.
What Is the Muse Wonder Context Window?
Both Muse Wonder and Muse Wonder Full handle about one million tokens of context. TechCrunch noted that Meta did not state the figure in its launch coverage, but Meta’s model card and Artificial Analysis both list one million.